How we judge a no-code app builder
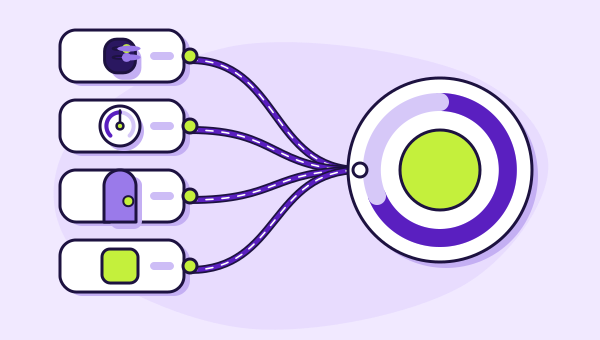
Four criteria, one rating, and a short list of things this desk refuses to do. Published so you can disagree with the method rather than argue with the conclusion.
On this page 5 sections
A rating is only useful if you can see what produced it. Here is the whole method, including the parts where judgement is involved and the parts where we decline to have an opinion.
The four criteria
Ceiling — how far the platform can be pushed. Can it hold real business rules, or does it start refusing once the requirements get interesting? This is the axis most reviews use exclusively, and it is worth roughly a quarter of our rating rather than all of it.
Legibility of the meter — can you reason about the bill? A platform that publishes what it counts, and what does not count, scores well here even if its prices are high. A platform that meters something it will not describe scores badly even if its entry tier is cheap. Predictability is a feature and it is priced as one.
Exit cost — what leaving would take. What is documented as exportable, where the data actually lives, and how much of the work would have to be recreated. A platform that never held your records is structurally better placed than one that did, and that shows up in the score.
Fit — how cleanly the platform matches a real shape of application. A narrow tool that is excellent at one shape can outscore a broad tool that is mediocre at everything, because you are buying for a specific job rather than for a general one.
Four inputs, one rating
- Ceilinghow far it can be pushed
- Legibility of the metercan you reason about the bill
- Exit costwhat leaving would take
- Fithow cleanly it matches a shape of app
One rating, 0 to 10
What the number means
Ratings run from 0 to 10 and the labels attached to them are deliberately about suitability rather than enthusiasm.
- 8.5 and above — build on it. Strong on capability, with a meter you can reason about and an exit that has been thought through.
- 7.5 to 8.4 — build, eyes open. A good platform with a named caveat you should read before committing.
- 6.5 to 7.4 — narrow fit. Right answer for a specific shape of application, wrong answer outside it.
- Below 6.5 — prototype only. Fine for proving an idea; not somewhere to put something a business depends on.
No platform is rated on how impressive its demo is, and none is penalised for being simple. Simplicity that is priced honestly beats capability that is priced opaquely, on this desk, every time.
The four bands, to scale
- Prototype only
- Narrow fit
- Build, eyes open
- Build on it
Where the figures come from
Every price, allowance, limit and quota is taken from the vendor's own pricing page or product documentation and recorded with a source and a date. Where a vendor's page could not be read directly — it happens, because pricing tables are frequently rendered in JavaScript — the copy says which documentation the figure came from instead of quietly using a third-party tracker.
Third-party price aggregators are not used as sources. In the course of building this site we found several that disagreed with each other and with the vendor about the same plan in the same month.
What this desk will not do
We do not estimate consumption. Not workload units per page load, not updates per user, not "a typical app costs about this much". No vendor publishes these figures and nobody outside your own account can produce them honestly. Where the cost is unpredictable, we say it is unpredictable and explain the mechanism.
We do not publish measurements we did not take. No load times for generated applications, no performance scores, no benchmark tables. This is a documentation-and-arithmetic desk, not a lab, and pretending otherwise would be the easiest way to be confidently wrong.
We do not invent users. No testimonials, no quoted customers, no composite case studies. If an example appears in a piece here, it is framed as an illustration of arithmetic, not as a person.
We do not soften a conclusion because a link is paid. Every outbound vendor link on this site is marked, and the affiliate disclosure explains the arrangement. A platform's rating is not affected by whether a programme exists, which is easy to claim and can at least be checked against the fact that the lowest-rated platform here carries the same kind of link as the highest.
When a rating changes
Ratings move when the evidence does. Over the period covered by the current set of pages, one vendor split into two products with two different meters, and another removed usage-based charging entirely. Both are exactly the sort of change that should move a score, and neither was announced to anybody who had already bought.
Every page carries the date its figures were last re-read. If the gap between that date and today has grown uncomfortable, check the vendor's page before acting on anything here — and if you find something stale, tell the desk, because that is the fastest way it gets fixed.
The ranked comparison that all of this feeds is the best no-code app builders.